No application changes
Your existing AI applications use RelAI without redesigning their business logic.
RelAI · by Itify
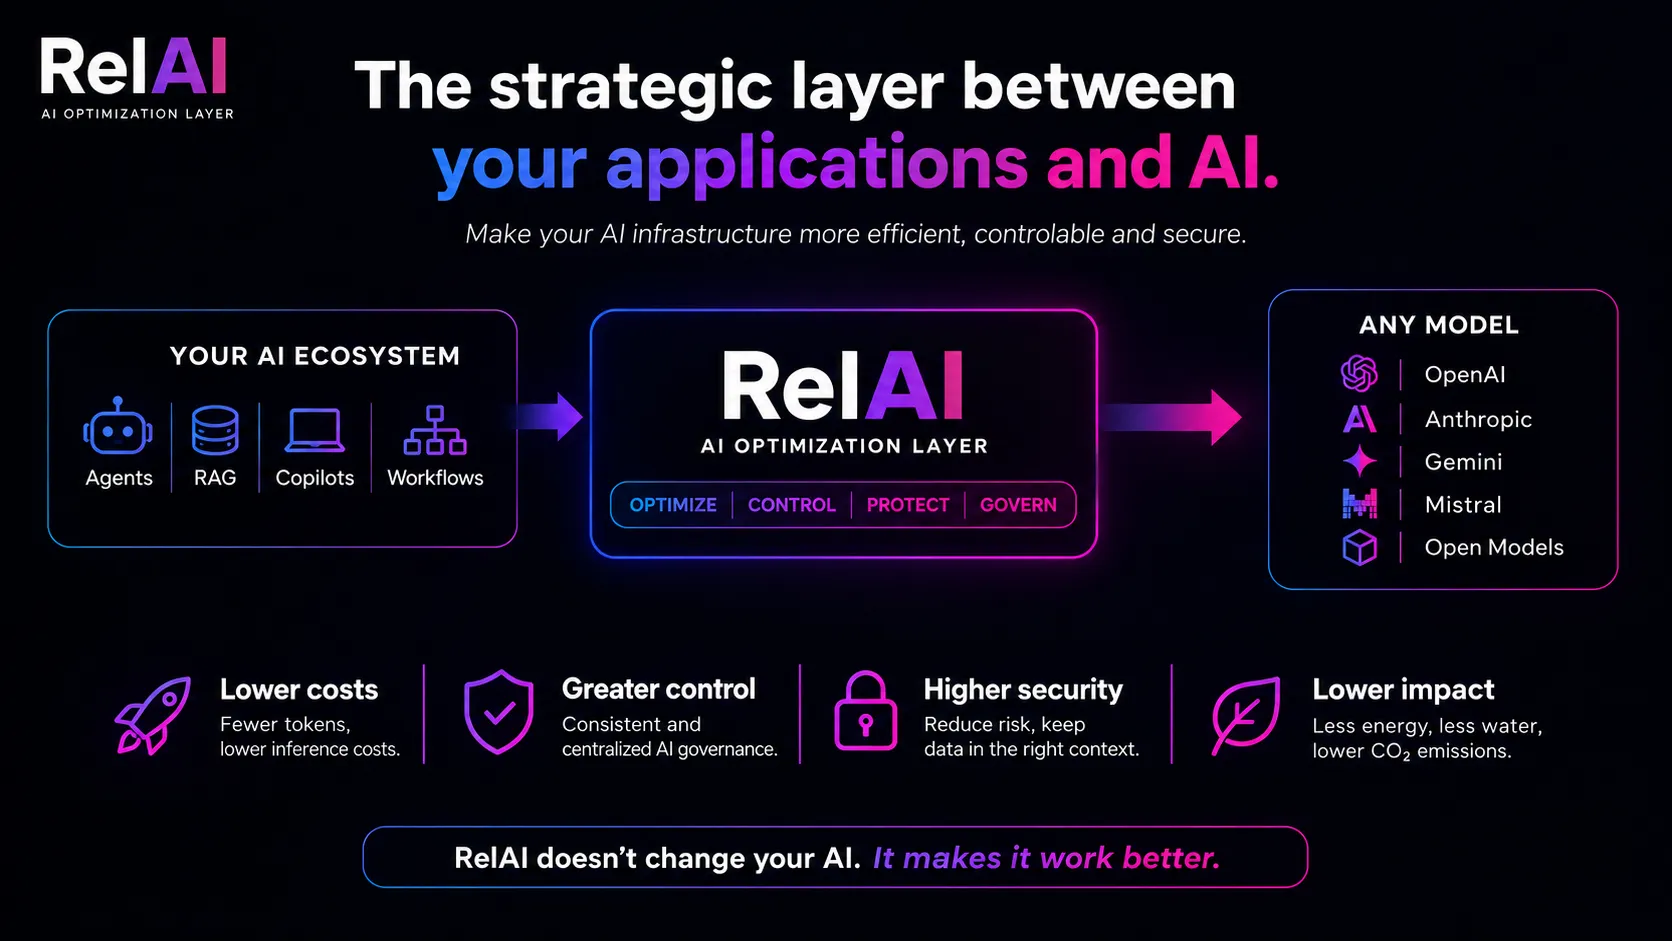
RelAI is the strategic layer between your applications and AI. It sits transparently between your software and any LLM, and reduces the tokens the model has to process without degrading output quality.
Reduce the cost. Preserve the intelligence.
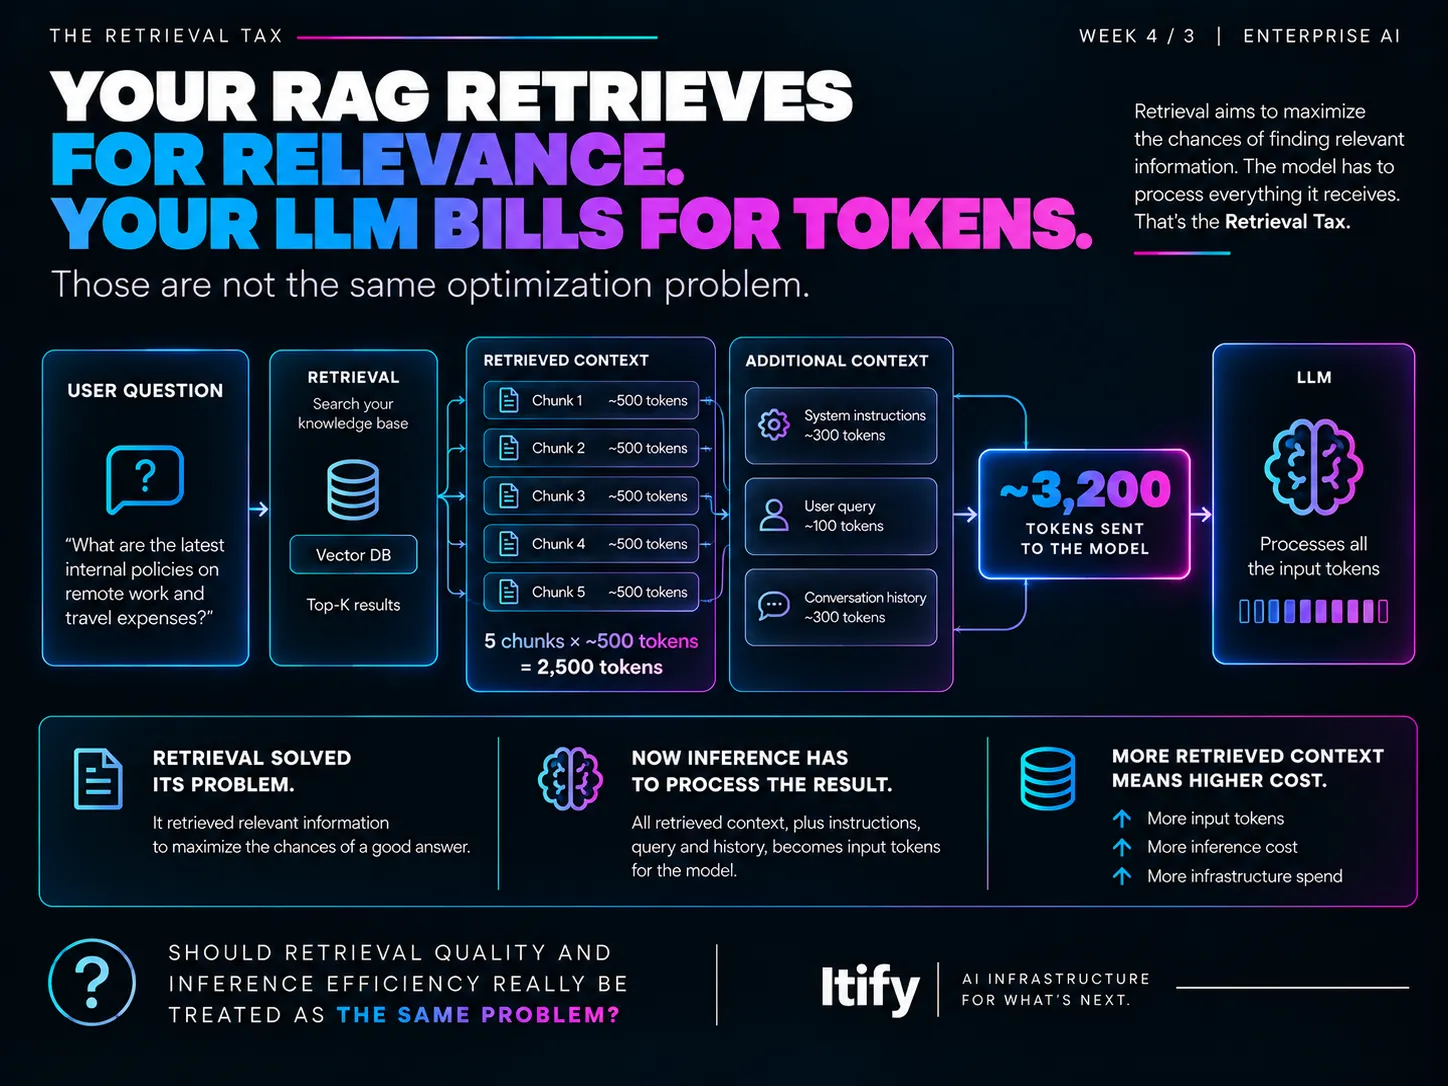
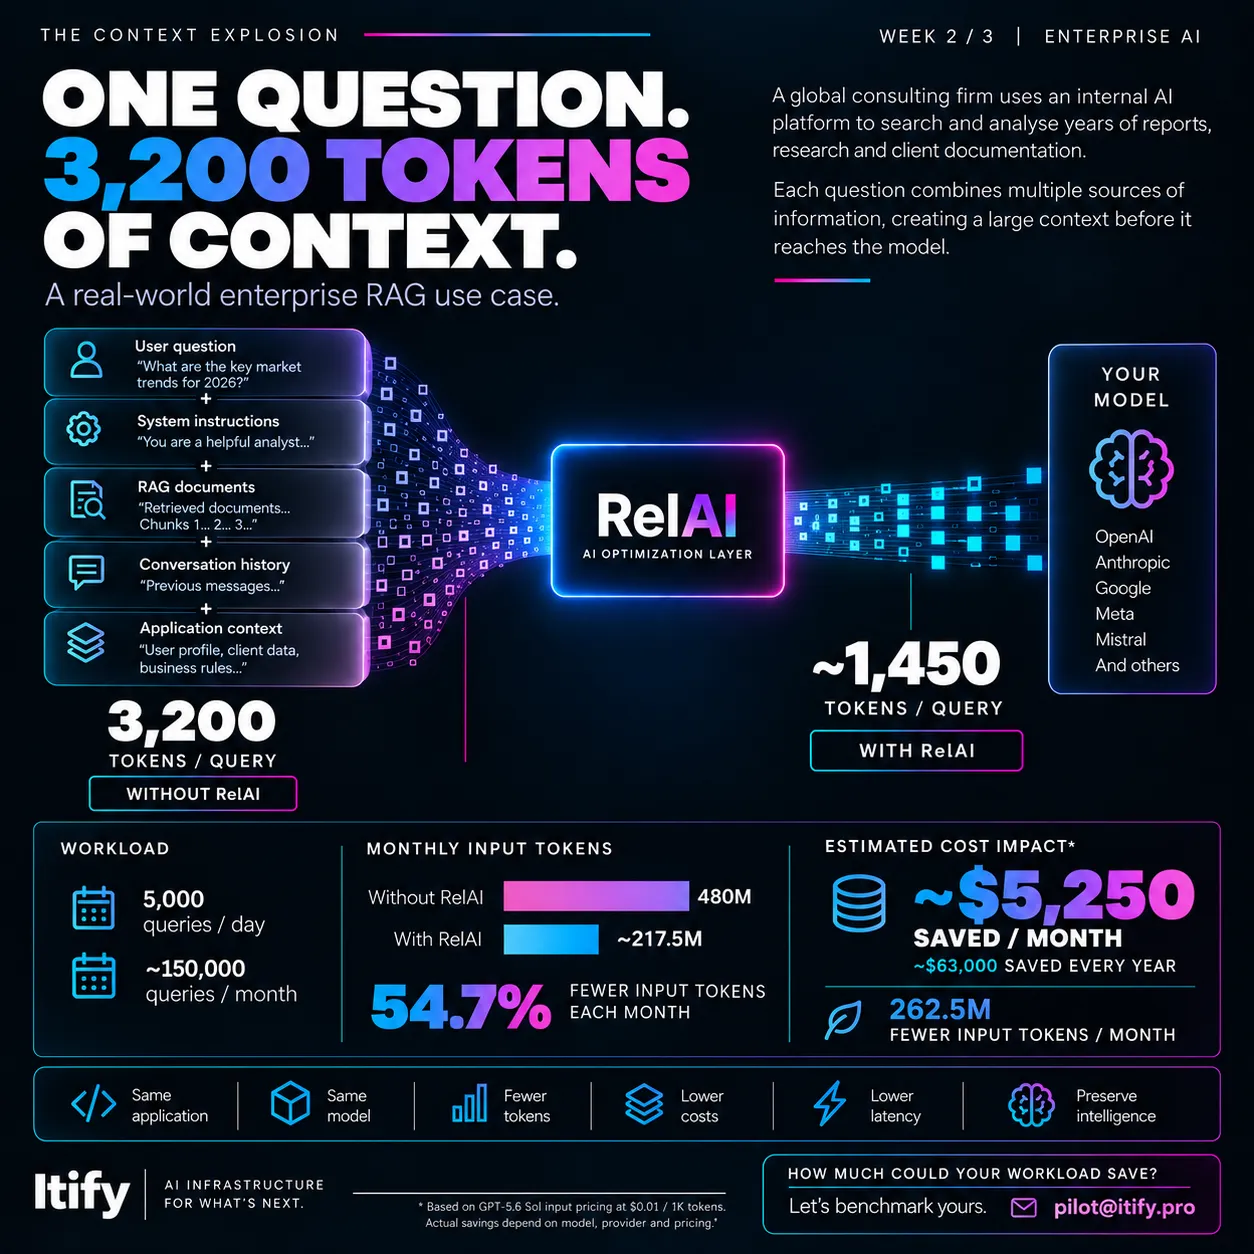
AI applications are evolving from simple prompts toward long contexts, RAG, agents, conversations and complex workflows. Every additional token has a computational and economic cost.
The current approach is, in effect, "send everything to the model and pay for everything." RelAI challenges that assumption.
RelAI analyzes the information being sent to the model and reduces unnecessary token consumption before inference. The model receives a more efficient representation of the required context. Your application keeps operating normally.
Your existing AI applications use RelAI without redesigning their business logic.
RelAI works with the LLMs you already use. No retraining, fine-tuning or replacing models. And no additional LLM calls.
You keep control over which models and providers you use. RelAI is an independent layer.
RelAI doesn't change your AI. It makes it work better.
Our real-world tests measure two things at once: token reduction and output quality. The goal is not to compress prompts, but to determine how much information can be removed without affecting the model’s ability to perform the task.
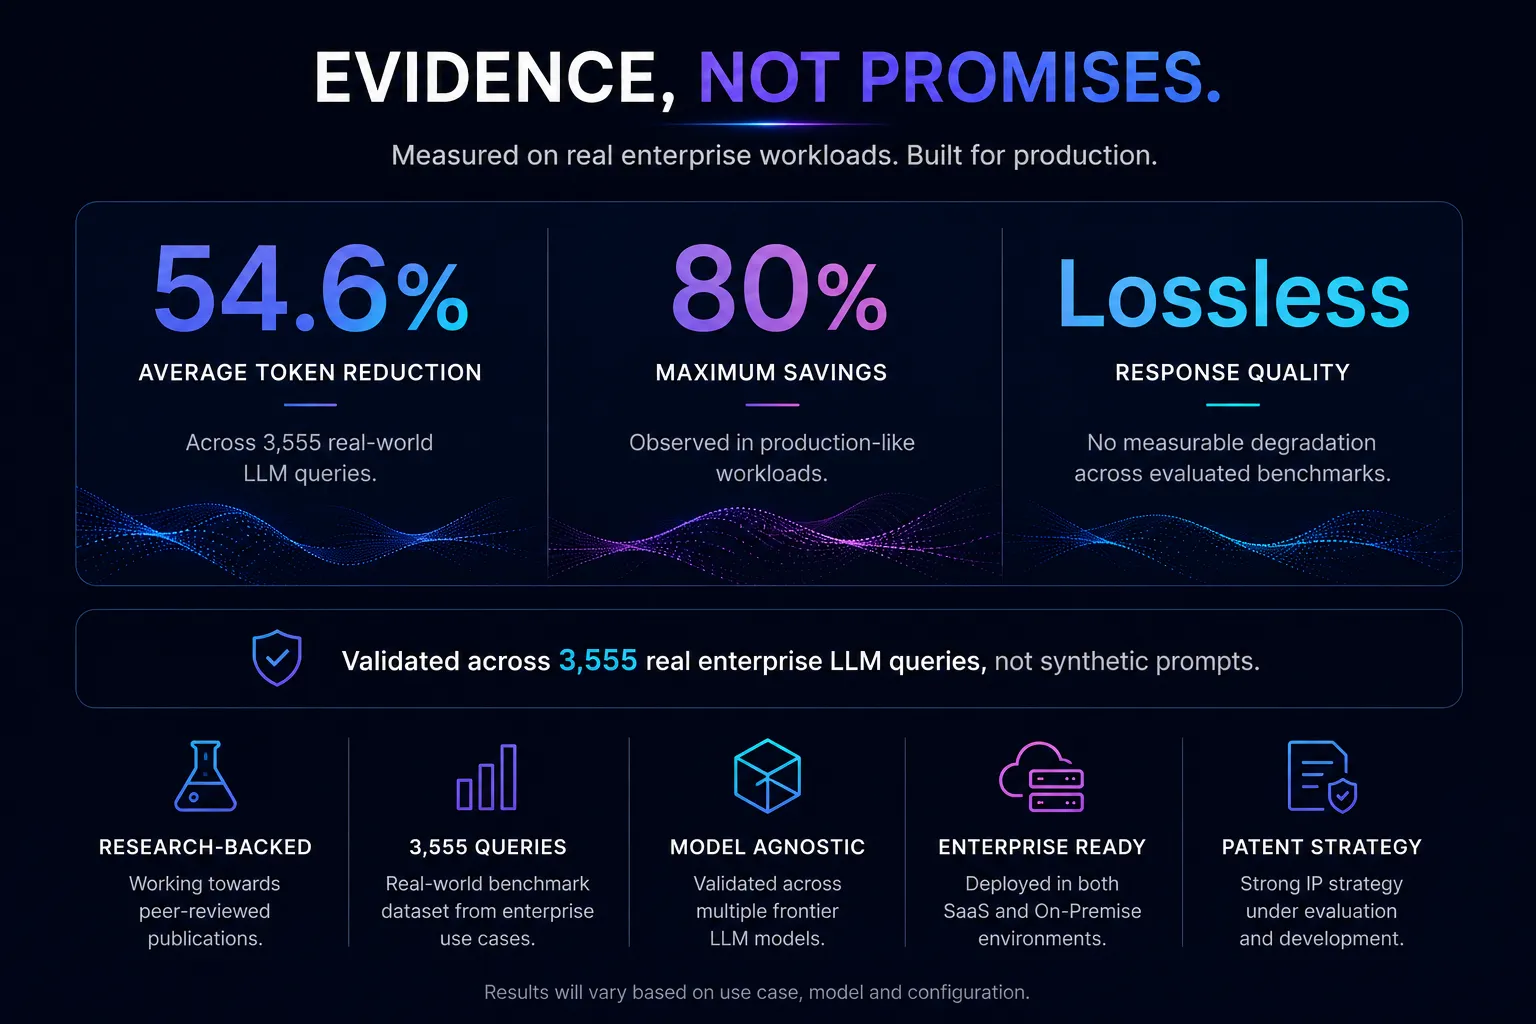
Average token reduction across 3,555 real-world LLM queries
Maximum savings observed in production-like workloads
No measurable degradation across evaluated benchmarks
Validated across 3,555 real enterprise LLM queries, not synthetic prompts.
Token volume processed by the model on a typical workload (−54.6%).
One of the key findings from our research is that optimization opportunity grows as prompts get longer. This matters strategically: AI systems are moving toward ever larger contexts, so RelAI becomes more valuable as your applications grow more complex.
Observed trend: the longer the context, the greater the optimization headroom.
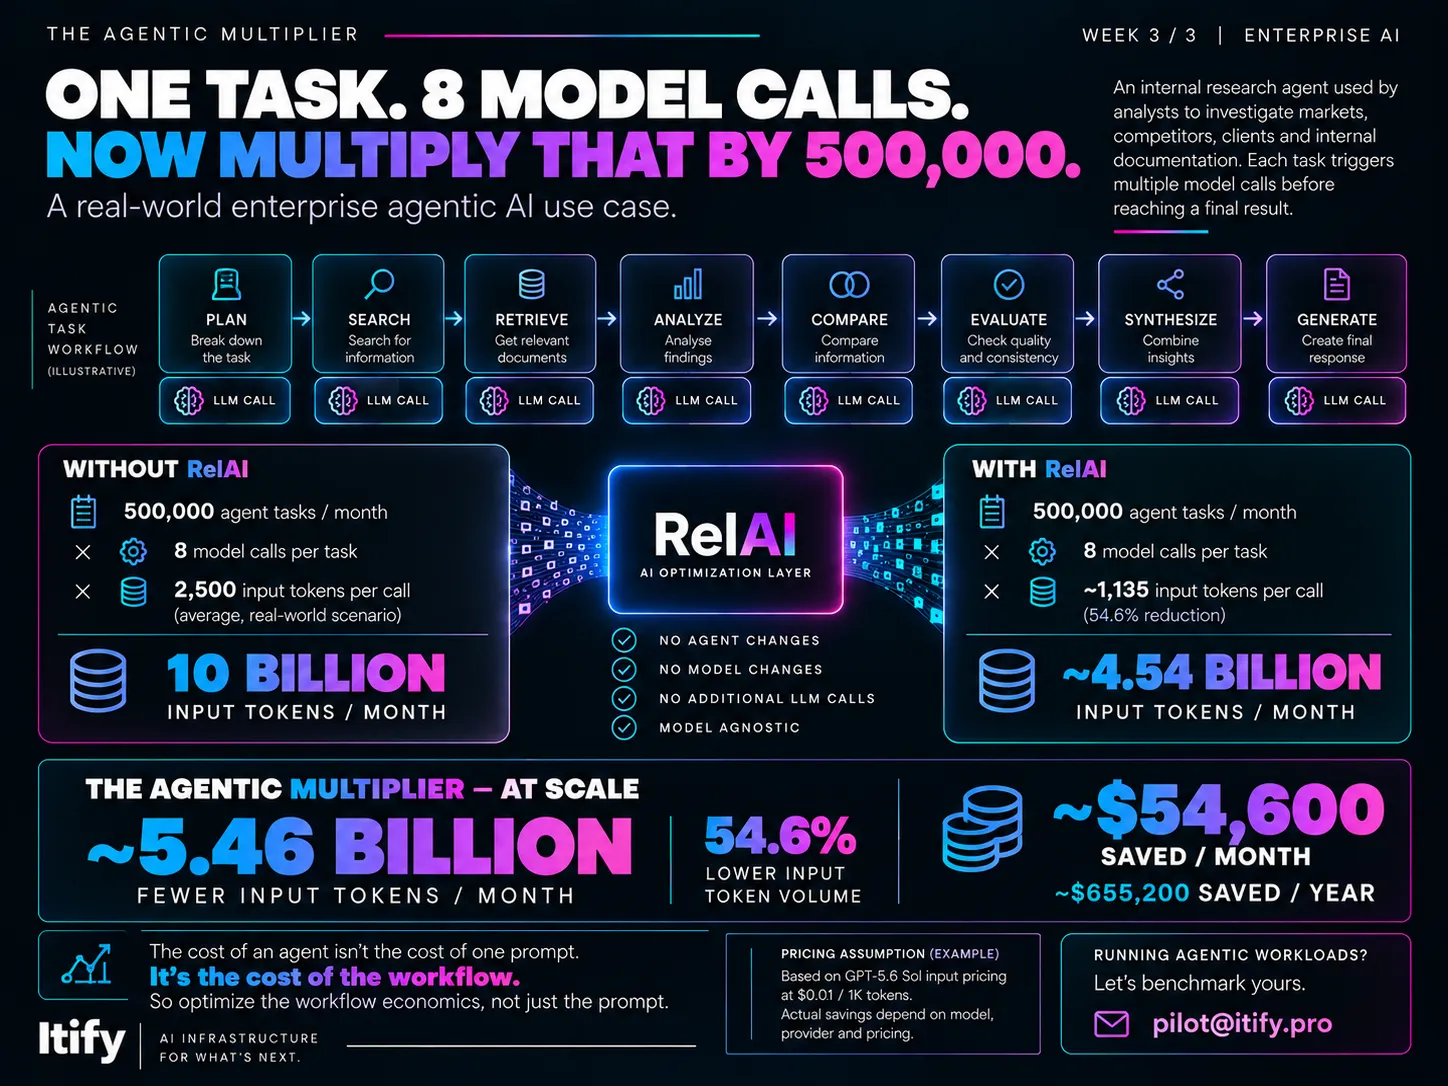
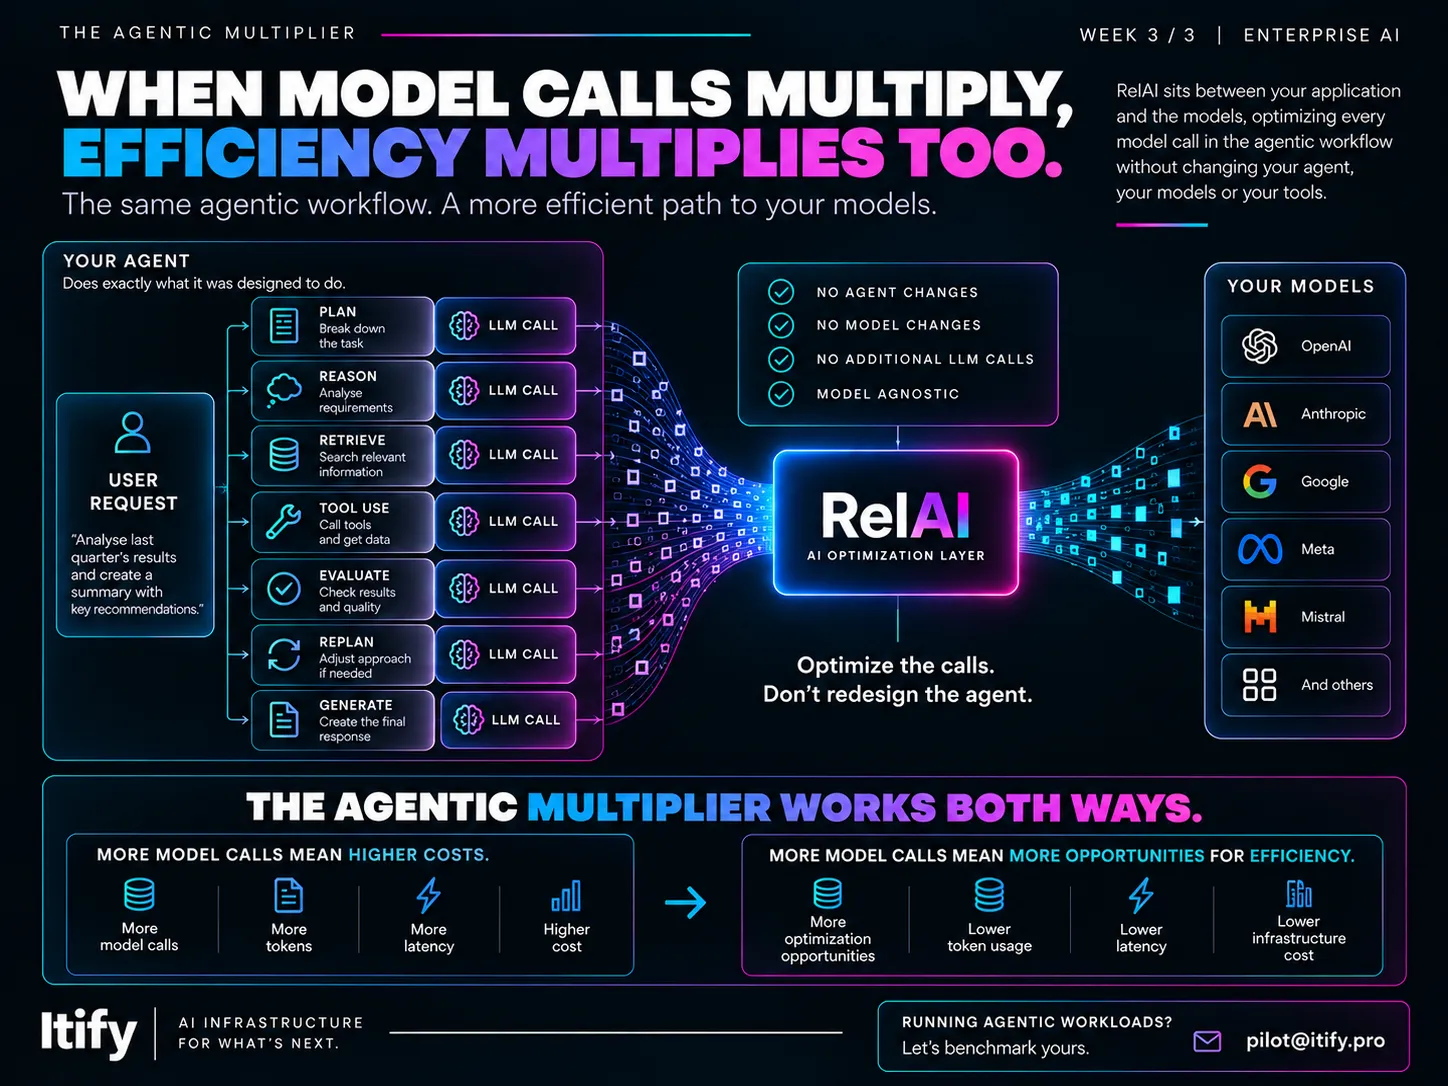
At small scale, the per-request saving looks insignificant. But an agentic task triggers several model calls, and that multiplies across millions of tasks per month. That is where the economic impact becomes substantial.
Illustrative case: an internal research agent runs 8 model calls per task, with 500,000 tasks per month.
| Without RelAI | With RelAI | |
|---|---|---|
| Agent tasks / month | 500,000 | 500,000 |
| Model calls / task | 8 | 8 |
| Input tokens / call | 2,500 | ~1,135 (−54.6%) |
| Input tokens / month | 10.0 B | ~4.54 B |
Fewer input tokens / month
Estimated savings / month
Estimated savings / year
The cost of an agent isn't the cost of one prompt: it's the cost of the whole workflow. Optimize the workflow economics, not just the prompt.
Example based on a reference input price ($0.01 / 1K tokens). Actual savings depend on the model, provider and pricing.
Adjust the variables to your case and estimate the savings. RelAI is model-agnostic: use the input price of whichever provider you prefer.
Indicative estimate. Actual savings depend on the workload type, the model and the configuration.
RelAI is validated through systematic benchmarking across real workloads and established benchmarks. We measure token reduction and output quality in parallel, and present results with statistical rigor.
Validated across 3,555 real enterprise LLM queries, not synthetic prompts.
Numerical reasoning · n=5 · mean ± std
No statistically significant difference in quality (McNemar’s test, p > 0.05).
8.5K math problems that test a model’s ability to reason with numbers.
Reading comprehension · n=5 · mean ± std
No statistically significant difference in quality (McNemar’s test, p > 0.05).
Reading-comprehension dataset with unanswerable questions.
Keeps model performance and accuracy.
Equivalent performance (McNemar’s test, p > 0.05).
Fewer tokens, lower cost, same intelligence.
Less energy, less water, fewer CO₂ emissions.
RelAI is working towards peer-reviewed publications, with a patent strategy under evaluation and development.
Make your AI infrastructure more efficient, controllable and secure. RelAI is model- and provider-agnostic, and deploys as SaaS or on-premise.
Fewer tokens, lower inference costs.
Consistent and centralized AI governance.
Reduce risk, keep data in the right context.
Less energy, less water, fewer CO₂ emissions.
Works with existing LLMs, without tying you to a model.
You decide which providers to use. RelAI belongs to none.
Cloud, private infrastructure or your own servers.
Built to run AI at scale in demanding corporate environments.
Vision
RelAI is the first component of a broader vision from Itify: AI infrastructure for what’s next.
As enterprise AI grows more complex, organizations will need an independent layer between their applications and their models. Optimization is the first problem RelAI solves; the long-term direction spans runtime efficiency, governance and enterprise AI operations.
What we share about inference efficiency, token economics and AI infrastructure at scale.
Tell us how you use AI today. We reply within 48 hours with an honest first read of the optimization headroom and how RelAI would fit into your infrastructure.